GLM is the family of large language models built by Z.ai, the company formerly known as Zhipu AI. GLM AI runs from GLM-5.3, a 744-billion-parameter flagship built for long coding and agent sessions, down to GLM-4.7-Flash, a 30B model that costs nothing on the official API. Most GLM models ship with open weights, most of them under the MIT license, and the newest ones read up to 1 million tokens of context in a single request.
The chat panel at the top of this page gives you nine GLM models in one place: GLM-5.3-Flash (the default), GLM-5.3, GLM-5.2, GLM-5.1, GLM-4.7, GLM-4.6, GLM-4.5, GLM-4.7-Flash and the GLM-Image generator. No account, no sign-up. This guide explains what each model is for, what the API costs, how GLM stacks up against ChatGPT, DeepSeek, Claude and Qwen, and every free route to GLM that exists today.
What is GLM?
GLM is a line of general-purpose AI models from Z.ai. You send text (and, with some models, images, video or files) and get text back: answers, code, summaries, translations, structured JSON or step-by-step plans. A separate model, GLM-Image, turns text prompts into pictures. Everything is available three ways: in a chat app, through a pay-as-you-go API, and as downloadable weights you can run on your own hardware.
The family is older than most people realise. Z.ai was founded in 2019 out of research at Tsinghua University. It introduced the original GLM pre-training approach in 2021, open-sourced GLM-130B (a 100B+ parameter model) in 2022 and launched ChatGLM in 2023. The open-source ChatGLM-6B was downloaded more than 20 million times. GLM-4 followed in January 2024, and the current generation started with GLM-4.5 in July 2025. Since then Z.ai has shipped a new flagship roughly every two months: GLM-4.6, GLM-4.7, GLM-5, GLM-5.1, GLM-5.2 and, in August 2026, GLM-5.3 and GLM-5.3-Flash. The full history lives on the GLM release timeline.
GLM release dates at a glance
| Release | Model | Headline change |
|---|---|---|
| Aug 26, 2026 | GLM-5.3-Flash | New 320B multimodal base model |
| Aug 14, 2026 | GLM-5.3 | Post-training upgrade, coding and cyber |
| Jun 16, 2026 | GLM-5.2 | 1M context, IndexShare |
| Apr 7, 2026 | GLM-5.1 | Up to 8-hour autonomous tasks |
| Mar 2026 | GLM-5-Turbo | GLM-5 tuned for OpenClaw |
| Feb 12, 2026 | GLM-5 | 744B parameters, sparse attention |
| Jan 19, 2026 | GLM-4.7-Flash | Free 30B model |
| Jan 14, 2026 | GLM-Image | Text-to-image with readable text |
| Dec 22, 2025 | GLM-4.7 | Turn-level thinking, better coding |
| Sep 30, 2025 | GLM-4.6 | Context 128K to 200K |
| Jul 28, 2025 | GLM-4.5 and GLM-4.5-Air | Hybrid reasoning, MoE design |
How GLM models are built
Every large GLM model since GLM-4.5 is a Mixture-of-Experts (MoE) model. The network holds a huge number of parameters, but each token only passes through a small slice of them. GLM-5.3 has 744B parameters in total and 40B active per token; GLM-4.5 has 355B total and 32B active. That design gives the model the knowledge of a very large network at the running cost of a much smaller one, which is a big reason GLM API prices sit well below closed frontier models.
The GLM-5 line added two efficiency tricks. GLM-5 was the first GLM to use DeepSeek Sparse Attention, which cuts the cost of long contexts. GLM-5.2 added IndexShare, which reuses one attention indexer across every four sparse-attention layers and, according to Z.ai, cuts per-token compute by 2.9x at a 1M-token context. GLM-5.3-Flash goes further with a hybrid of linear and sparse attention, the first in the series, and needs 4.4x less KV-cache memory than GLM-5.3.
Thinking models with an effort dial
Current GLM models are reasoning models: they can “think” (write out hidden reasoning) before they answer. On the API you control this with a thinking parameter and, on the newest models, a reasoning_effort setting. GLM-5.3 and GLM-5.3-Flash always think and accept low, high or max effort. GLM-5.2 accepts high or max. Older models such as GLM-4.7 let you switch thinking off completely for fast, cheap answers. The GLM thinking mode guide has the full per-model breakdown.
What GLM is good at
- Coding and coding agents. This is where Z.ai puts most of its effort. GLM-5.3 posts 88.2 on Terminal Bench 2.1 and 66.9 on DeepSWE v1.1 in Z.ai’s published results, and GLM plugs straight into Claude Code, Cline, OpenCode, Cursor and other tools.
- Long-horizon work. GLM-5.1 can work on a single task for up to 8 hours, and GLM-5.2 and later hold a 1M-token context, enough for a large codebase or a stack of long documents.
- Math and science reasoning. Z.ai reports 99.2 on AIME 2026 and 91.2 on GPQA-Diamond for GLM-5.2.
- Tool use. Function calling, structured JSON output, streaming tool calls and a built-in web search tool are all supported on the API.
- Vision. GLM-5.3-Flash reads images, video and files natively; GLM-4.6V and GLM-4.5V are dedicated vision models.
- Text inside images. GLM-Image is built to render readable text on posters, slides and diagrams.
How GLM Chat fits in
GLM Chat is a free front door to these models. Pick a model chip, type up to 8,000 characters and send. The paid models allow 40 messages per day per visitor; GLM-4.7-Flash is unlimited (one request every 3 seconds at most), and GLM-Image makes up to 3 pictures a day. GLM-5.3-Flash also accepts image uploads (JPEG, PNG or WebP up to 4 MB). Your conversations stay in your own browser, up to 30 of them, and the server keeps only anonymous counters. If you want to jump straight to a specific model, use a deep link such as chat with GLM-5.3 or chat with the free GLM-4.7-Flash.
Every GLM model explained
Here is the whole current lineup, newest first. Each entry links to a full page with specs, benchmarks, API code and pricing. For a single side-by-side table of every model, go to GLM models compared.
GLM-5.3: the flagship
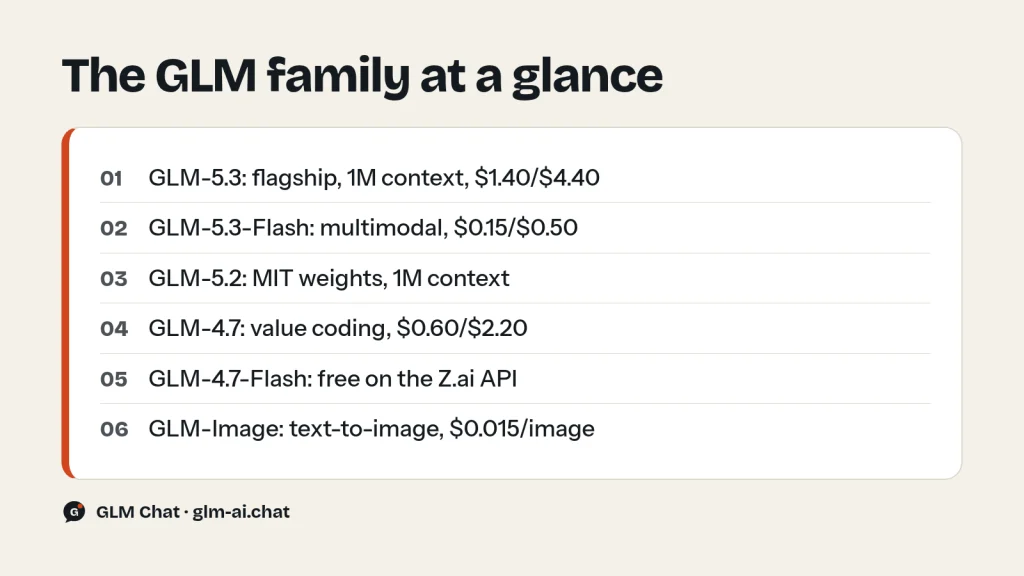
Z.ai announced GLM-5.3 on August 14, 2026 and published the weights on Hugging Face on August 25. It uses the same 744B-total, 40B-active base model as GLM-5.2; every improvement comes from post-training. Z.ai reports a 50% gain over GLM-5.2 on its in-house Z.ai Code Bench and open-source state-of-the-art results on Terminal Bench 3.0 and Agents’ Last Exam. It is also the top scorer on the CyberGym vulnerability-discovery benchmark at 84.5%. GLM-5.3 takes text only, reads 1M tokens, writes up to 128K, and always thinks. The API price is $1.40 per million input tokens and $4.40 per million output tokens. The weights use a custom GLM-5.3 License (details below).
GLM-5.3-Flash: cheap, fast and multimodal
GLM-5.3-Flash launched on August 26, 2026 and is the default model in GLM Chat. It is a brand-new 320B-total, 18B-active model and the first natively multimodal model in the GLM-5 series: it accepts text, images, video and files. It keeps the 1M context and 128K output of its big sibling at $0.15 in and $0.50 out, and Z.ai says it beats GLM-5.2 on six coding and agent benchmarks. Before launch it ran anonymously on OpenRouter and OpenCode as “ox-alpha”. Weights are MIT-licensed. A paid speed variant, GLM-5.3-FlashX, runs at about 200 tokens per second for $0.37 in and $1.25 out.
GLM-5.2: the 1M-context open model
GLM-5.2 arrived on June 16, 2026 with open weights the same day under the MIT license. It was the first GLM with what Z.ai calls a “solid 1M lossless context”, built for long-horizon tasks. It introduced IndexShare, an improved multi-token prediction layer for faster decoding, and two effort levels (High and Max). Z.ai reports 62.1 on SWE-bench Pro and 81.0 on Terminal Bench 2.1. Price: $1.40 in, $4.40 out. On the Coding Plan, GLM-5.2 requests now route to GLM-5.3, but the API and the MIT weights remain available.
GLM-5.1: the eight-hour worker
GLM-5.1 (April 7, 2026) is a 744B-A40B MIT model with a 200K context and 128K output. Z.ai built it to keep improving over long agent runs: it can work on one task for up to 8 hours, and Z.ai showed it lifting vector-database query throughput to 6.9x over 655 iterations. It scored 58.4 on SWE-bench Pro at launch. Unlike GLM-5.3, it lets you switch thinking off. Same price as GLM-5.2 and GLM-5.3.
GLM-5 and GLM-5-Turbo
GLM-5 (February 12, 2026) started the GLM-5 line. It scaled the architecture from 355B to 744B parameters, raised pre-training data from 23T to 28.5T tokens, and became the first GLM to use DeepSeek Sparse Attention. Z.ai reports 77.8 on SWE-bench Verified and first place among open-source models on Vending Bench 2. At $1.00 in and $3.20 out, it is the cheapest 744B GLM on the API. GLM-5-Turbo is a GLM-5 variant tuned for OpenClaw agent workflows (tool calls, long instruction chains, scheduled tasks); its weights are not published and it is not on Z.ai’s public price list, while OpenRouter lists it at $1.20 in and $4.00 out.
GLM-4.7: the last big 4.x model
GLM-4.7 (December 22, 2025) keeps the 355B-class, 32B-active design of GLM-4.5 but sharpens coding: Z.ai reports 73.8% on SWE-bench Verified and 84.9 on LiveCodeBench v6. It introduced turn-level thinking, so you can decide per turn whether the model reasons. 200K context, 128K output, MIT license, and $0.60 in and $2.20 out, which makes it a strong value pick for everyday coding.
GLM-4.7-Flash: the free one
GLM-4.7-Flash (January 19, 2026) is the free-tier version of GLM-4.7: a 30B-A3B MoE model (31B total) with a 200K context and 128K output. Input, cached input and output all cost $0 on the Z.ai API. Its model card reports 59.2 on SWE-bench Verified and 91.6 on AIME 25. It runs locally with vLLM and SGLang and is the most downloaded GLM repository on Hugging Face at more than 1.8 million downloads a month. In GLM Chat it has no daily cap.
GLM-4.6: the 200K upgrade
GLM-4.6 (September 30, 2025) raised the context from 128K to 200K and, according to Z.ai, uses over 30% fewer tokens than GLM-4.5 for the same work. Z.ai tested it in 74 real coding tasks inside Claude Code and published the trajectories. Hybrid thinking is on by default. Price: $0.60 in, $2.20 out. Its vision sibling GLM-4.6V reads images and video with a 128K context. There is no “GLM-4.6 Air”; the lightweight open model from that period is GLM-4.5-Air.
GLM-4.5: where the modern line began
GLM-4.5 (July 28, 2025) is a 355B-total, 32B-active MoE model with a 128K context and 96K output, released under MIT. At launch Z.ai ranked it second overall and first among open-source models on the average of 12 benchmarks. It introduced hybrid reasoning, with a thinking mode for hard problems and a non-thinking mode for instant replies. The GLM-4.5 series also includes the paid speed variants GLM-4.5-X and GLM-4.5-AirX and the free GLM-4.5-Flash.
GLM-4.5-Air: the lightweight open model
GLM-4.5-Air shares GLM-4.5’s release date, training recipe and 128K context but shrinks to 106B total and 12B active parameters. It costs $0.20 in and $1.10 out on the API, and its MIT weights make it one of the more practical GLM models to self-host.
GLM-Image: text-to-image with readable text
GLM-Image (January 14, 2026) pairs a 9B autoregressive model with a 7B diffusion decoder and a Glyph Encoder for lettering. It is aimed at images that contain text, such as posters, slides and diagrams, and posts a CVTG-2K word accuracy of 0.9116. It costs $0.015 per image on the API, weights are MIT, and the image link the API returns expires after 30 days. In GLM Chat you can generate images with GLM-Image (3 per day) and download each result.
Vision, OCR and speech models
Around the main line sit several specialist models, all on the same API. GLM-4.6V (December 8, 2025) reads images, video, text and files with a 128K context and native function calling, for $0.30 in and $0.90 out; GLM-4.6V-FlashX is its fast, cheap variant and GLM-4.6V-Flash is free. GLM-4.5V is an earlier 100B-scale open vision reasoning model. GLM-5V-Turbo is a multimodal coding model with a 200K context, built for agents that need to look at screens. GLM-OCR parses documents for $0.03 per million tokens, and GLM-ASR-2512 transcribes speech for about $0.0024 per minute.
Quick pick: which GLM model for which job
| Job | Best GLM model | Why |
|---|---|---|
| Everyday questions and writing | GLM-5.3-Flash | Fast, cheap, reads images |
| Hard coding and long agent runs | GLM-5.3 | Strongest coding scores |
| Whole-repo or long-document work | GLM-5.2 or GLM-5.3 | 1M-token context |
| Fast answers without reasoning | GLM-4.7 or GLM-5.2 | Thinking can be switched off |
| Free, high-volume API use | GLM-4.7-Flash | $0 per token |
| Self-hosting on modest hardware | GLM-4.7-Flash or GLM-4.5-Air | 3B or 12B active parameters |
| Posters, slides, diagrams | GLM-Image | Accurate text in images |
GLM vs ChatGPT, DeepSeek, Claude and Qwen
The fairest comparison uses one set of numbers run under one setup. The benchmark rows below come from Z.ai’s own published tables for GLM-5.3 and GLM-5.2, which include GPT-5.6 Sol and GPT-5.5 (the models behind ChatGPT), DeepSeek-V4-Pro, Claude Opus 4.8 and Qwen3.8-Max / Qwen3.7-Max. They are Z.ai-reported, not independent. Prices come from each vendor’s official pricing page. A dash means no official figure is available to cite here.
| Compared | GLM | ChatGPT / GPT | DeepSeek | Claude | Qwen |
|---|---|---|---|---|---|
| Model compared | GLM-5.3 | GPT-5.6 Sol | DeepSeek-V4-Pro-0813 | Claude Opus 4.8 | Qwen3.8-Max |
| Open weights | Yes (GLM-5.3 License; MIT for most GLMs) | — | Yes | No | — |
| Context window | 1M | — | 1M | — | — |
| API price per 1M (in / out) | $1.40 / $4.40 | — | $1.32 / $3.96 (peak) | $5 / $25 | — |
| Free access | GLM Chat, chat.z.ai, free Flash API models | — | — | — | — |
| Terminal Bench 2.1 | 88.2 | 88.8 | 87.9 | 85.0 | 86.6 |
| HLE with tools | 62.5 | 64.5 | 60.0 | 57.9 | 56.2 |
| CyberGym | 84.5 | 83.6 | 83.3 | 78.1 | 78.5 |
| DeepSWE v1.1 | 66.9 | 72.7 | 62.7 | 58.0 | 56.6 |
| SWE-bench Pro (GLM-5.2 table) | 62.1 (GLM-5.2) | 58.6 (GPT-5.5) | 55.4 (V4-Pro) | 69.2 | 60.6 (Qwen3.7-Max) |
What the table says in plain terms:
- GLM vs ChatGPT. In Z.ai’s GLM-5.3 table, GPT-5.6 Sol is slightly ahead on most agent and coding rows (Terminal Bench 2.1, DeepSWE, HLE with tools), while GLM-5.3 wins CyberGym, AutomationBench, PostTrainBench and GDPval-AA v2. The practical difference is access: GLM-5.3 weights are downloadable and its API price is published at $1.40 / $4.40.
- GLM vs DeepSeek. The closest match. Both offer open weights, 1M context, thinking modes, JSON output, tool calls and an Anthropic-compatible endpoint. DeepSeek-V4-Pro is slightly cheaper at peak ($1.32 / $3.96) and half price off-peak; GLM-5.3 edges it on most rows in Z.ai’s table. Full breakdown: GLM vs DeepSeek.
- GLM vs Claude. Claude Opus 4.8 leads on SWE-bench Pro and NL2Repo in Z.ai’s tables, but costs $5 / $25 per million tokens and has no open weights. GLM-5.3 beats it on Terminal Bench 2.1, CyberGym and HLE with tools. Many developers use both: GLM runs inside Claude Code through Z.ai’s Coding Plan. See GLM vs Claude.
- GLM vs Qwen. In Z.ai’s GLM-5.3 table, GLM-5.3 leads Qwen3.8-Max on every row where both have a score; the closest are Toolathlon Verified (73.0 vs 72.5) and GDPval-AA v2 (1769 vs 1739). The older generation was tighter: in the GLM-5.2 table, Qwen3.7-Max edges GLM-5.2 on HLE (41.4 vs 40.5) and both HMMT math rows. Qwen’s pricing and license are outside the scope of Z.ai’s tables, so check them on Qwen’s own pages.
Price is where the gap is widest. One million input tokens plus one million output tokens costs $5.80 on GLM-5.3, $0.65 on GLM-5.3-Flash, $5.28 on DeepSeek-V4-Pro at peak ($2.64 off-peak) and $30 on Claude Opus 4.8. Real workloads usually read far more than they write, and cached input cuts GLM’s input price further, to $0.26 per million on GLM-5.3.
The honest summary: on Z.ai’s numbers GLM-5.3 sits in the same band as the closed frontier on agentic coding, a step behind the very top models on the hardest rows, at a fraction of the closed-model price and with weights you can download. The best way to judge is on your own prompts, and every model page on this site includes a five-task test run in GLM Chat’s own harness.
How to use GLM for free
GLM free access is real, not a trial. There are four routes, and you can mix them.

- GLM Chat (this site). Open the free GLM chat, pick a model and type. Nine models, no account. Limits: 40 messages a day per visitor on paid models, unlimited GLM-4.7-Flash (one request every 3 seconds), 3 GLM-Image pictures a day, 8,000 characters per message. When the site’s daily capacity runs out, paid models fall back to GLM-4.7-Flash until the next UTC day and the reply tells you so.
- Z.ai’s chat app. chat.z.ai is Z.ai’s own free web chat with GLM models, including the flagship GLM-5.3.
- Free API models. Three models cost $0 on the Z.ai API for input, cached input and output: GLM-4.7-Flash, GLM-4.5-Flash and the vision model GLM-4.6V-Flash. You still need an API key, and your account’s rate limits apply (see them at z.ai/manage-apikey/rate-limits).
- OpenRouter’s free variant. OpenRouter lists
z-ai/glm-5.2:freeat $0 with a 32,768-token context. It is rate-limited and far shorter than GLM-5.2’s native 1M context, but it is a quick way to try a 744B GLM model from any OpenAI-compatible client.
Be precise about GLM-5.3-Flash: it is free to use in GLM Chat, where it is the default model, but it is not free on the Z.ai API. There it costs $0.15 per million input tokens and $0.50 per million output tokens, cheap but not zero. If you need a truly free API model, use GLM-4.7-Flash. The GLM pricing guide covers every price and a few worked cost examples.
Getting the most from GLM Chat
- Start on GLM-5.3-Flash. It is the default for a reason: quick, capable and the only chip that accepts image uploads.
- Switch to GLM-5.3 for hard problems. Tricky debugging, multi-file refactors and long reasoning chains are where the flagship pulls ahead.
- Use GLM-4.7-Flash for volume. It has no daily cap, so drafts, rewrites and quick lookups belong there.
- Keep context tight. The chat sends your last 20 messages (up to 24,000 characters) with each request. Start a new conversation when you change topic.
- Keep private data out. Messages pass through this site’s server to Z.ai’s API to generate the reply, so leave passwords and personal data out of your prompts.
- Share a model. Deep links such as chat with GLM-5.2 open the chat with that model already selected.
The chat uses fixed settings that suit most questions: temperature 0.7, up to 2,048 output tokens, and the lightest reasoning setting each model allows (thinking off where possible, low effort on GLM-5.3 and GLM-5.3-Flash). For very long outputs or maximum-effort reasoning, call the API directly.
Which free option should you pick?
| You want to | Use |
|---|---|
| Ask a question right now | GLM Chat, GLM-5.3-Flash |
| Chat without any daily cap | GLM Chat, GLM-4.7-Flash |
| Analyse a screenshot or photo | GLM Chat, GLM-5.3-Flash with image upload |
| Build an app at zero cost | Z.ai API, glm-4.7-flash |
| Free vision in your code | Z.ai API, glm-4.6v-flash |
| Try a 744B model from code | OpenRouter, z-ai/glm-5.2:free |
GLM API in 5 minutes
The Z.ai API speaks the OpenAI Chat Completions format, so any OpenAI client works once you change the base URL and the model name. The examples below use glm-4.7-flash because it is free, so your first calls cost nothing. Swap in glm-5.3 or glm-5.3-flash when you need more power.
- Create a Z.ai account and open the API Keys page at z.ai/manage-apikey/apikey-list. Create a new key.
- Store it in an environment variable, for example
export ZAI_API_KEY=your-api-key. Never paste a key into shared code. - Send requests to the base URL
https://api.z.ai/api/paas/v4, endpoint/chat/completions, with the headerAuthorization: Bearer $ZAI_API_KEY.
First request with curl
curl -X POST "https://api.z.ai/api/paas/v4/chat/completions" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $ZAI_API_KEY" \
  -d '{
    "model": "glm-4.7-flash",
    "messages": [
      {"role": "user", "content": "Explain what a mixture-of-experts model is in three sentences."}
    ],
    "thinking": {"type": "disabled"},
    "max_tokens": 1024
  }'
The answer is in choices[0].message.content. Setting thinking to disabled gives a faster, shorter reply; leave it out (thinking is on by default for the GLM-4.7 series) when you want the model to reason first.
Python with the OpenAI SDK
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("ZAI_API_KEY"),
    base_url="https://api.z.ai/api/paas/v4/",
)

stream = client.chat.completions.create(
    model="glm-5.3-flash",
    messages=[{"role": "user", "content": "Write a haiku about open weights."}],
    reasoning_effort="low",
    stream=True,
)

for chunk in stream:
    delta = chunk.choices[0].delta
    if delta.content:
        print(delta.content, end="", flush=True)
This example switches to GLM-5.3-Flash (paid, $0.15 / $0.50) to show two things. First, GLM-5.3 and GLM-5.3-Flash always think, so you control speed with reasoning_effort (low, high or max, default max). Never send "thinking": {"type": "disabled"} to glm-5.3: the request fails. Second, when streaming, the reasoning arrives in delta.reasoning_content and the answer in delta.content, and the stream ends with data: [DONE]. Z.ai also ships an official Python SDK (pip install zai-sdk) if you prefer it.
Send an image to GLM-5.3-Flash
GLM-5.3-Flash takes images through the same endpoint. Add an image_url part to the message content; the URL can be a public link or a base64 data URL, and you can include several images in one message.
response = client.chat.completions.create(
    model="glm-5.3-flash",
    messages=[{
        "role": "user",
        "content": [
            {"type": "image_url", "image_url": {"url": "https://example.com/chart.png"}},
            {"type": "text", "text": "Summarise what this chart shows."},
        ],
    }],
    reasoning_effort="low",
)
print(response.choices[0].message.content)
Four mistakes that break a first GLM request
- Wrong base URL. Pay-as-you-go calls go to
https://api.z.ai/api/paas/v4. The/api/coding/paas/v4and/api/anthropicURLs are for Coding Plan tools. Mixing the two up is a common cause of error 1113 (insufficient balance). - Capitalised model names. Model IDs are lowercase:
glm-5.3, notGLM-5.3. An unknown model returns error 1211. - Disabling thinking on GLM-5.3. Send
reasoning_effort: "low"instead. - Temperature above 1.0. The Z.ai API accepts 0.0 to 1.0 only, so values copied from other providers can trigger a 400 error.
Which model ID to use
| Model ID | Best for | Price in / out per 1M |
|---|---|---|
glm-5.3 | Hard coding and agent work | $1.40 / $4.40 |
glm-5.3-flash | Cheap default, images and video | $0.15 / $0.50 |
glm-5.2 | 1M context, thinking can be skipped | $1.40 / $4.40 |
glm-4.7 | Value coding, full thinking control | $0.60 / $2.20 |
glm-4.7-flash | Free prototyping and high volume | Free |
glm-image | Image generation (images endpoint) | $0.015 per image |
Temperature on the Z.ai API ranges from 0.0 to 1.0 (default 1.0 on GLM-5.x and GLM-4.7). If a request fails with HTTP 429 and code 1302, you hit your rate limit; 1113 means no balance or resource package. The full GLM API quickstart adds Node.js, streaming parsing and an OpenAI migration checklist, and the rate limits and error codes guide covers every error.
GLM Coding Plan
The GLM Coding Plan is Z.ai’s subscription for coding agents. Instead of paying per token, you pay a monthly fee and spend credits inside supported tools: ZCode, AutoClaw, Claude Code, Codex, Cursor, OpenCode, OpenClaw, Cline, Kilo Code, Roo Code and others. Since July 30, 2026 it is credits-based.
| Tier | Monthly | Yearly (per month) | Credits per 5 hours | Credits per week |
|---|---|---|---|---|
| Lite | $18 | $12.60 | 2,000 | 10,000 |
| Pro | $80 | $56 | 12,000 | 60,000 |
| Max | $168 | $117.60 | 28,000 | 140,000 |
How it works in practice:
- Models. Every tier gets GLM-5.3 and GLM-5.3-Flash. Requests for GLM-5.2 or GLM-5.1 are routed to GLM-5.3, and GLM-4.7 requests go to GLM-5.3-Flash. GLM-5.3-Flash gets 3x the quota of GLM-5.3.
- Credits. Cost per call = (input tokens x input multiplier + cached tokens x cached multiplier + output tokens x output multiplier) / 10,000. For GLM-5.3 the multipliers are 6.9, 1.7 and 24; for GLM-5.3-Flash 2.3, 0.56 and 8.
- Off-peak discount. Calls outside peak hours (Monday to Friday, 14:00 to 18:00 UTC+8) cost 50% of the credits, and weekends are off-peak all day.
- Tools only. Plan quota works inside supported coding tools, never for general API calls, and never draws on your pay-as-you-go balance. Claude Code connects through
https://api.z.ai/api/anthropic; OpenAI-compatible tools usehttps://api.z.ai/api/coding/paas/v4. - Extras. All plans include the Vision Understanding, Web Search, Web Reader and Zread MCP servers.
A worked credit example
Take a typical agent step on GLM-5.3: 10,000 fresh input tokens, 40,000 cached input tokens (the part of the conversation the model has already seen) and 2,000 output tokens. The cost is (10,000 x 6.9 + 40,000 x 1.7 + 2,000 x 24) / 10,000 = (69,000 + 68,000 + 48,000) / 10,000 = 18.5 credits at peak, or 9.25 credits off-peak. A Lite plan’s 2,000 credits per 5 hours covers about 108 such steps at peak, and its 10,000 weekly credits about 540. The same step on GLM-5.3-Flash costs (23,000 + 22,400 + 16,000) / 10,000 = 6.14 credits, three times cheaper.
Z.ai estimates a Lite plan covers roughly 48 to 97 million GLM-5.3 tokens a week at a 95% cache hit rate (the range runs from all-peak to all-off-peak use), and claims savings of up to 92% against pay-as-you-go GLM-5.3. Subscriptions are non-refundable, so start with Lite. Read the GLM Coding Plan guide for the break-even math, then follow the GLM in Claude Code setup or the GLM in Cline guide.
Is GLM open source?
Mostly yes. Z.ai publishes weights for nearly every major GLM model on Hugging Face (organisation zai-org) and ModelScope (organisation ZhipuAI), and most of them use the MIT license, which lets you use, modify, fine-tune, redistribute and sell products built on the model with almost no strings attached. The GLM-5 technical report, GitHub code and serving recipes are public too.
| Model | Weights | License |
|---|---|---|
| GLM-5.3 | Open (FP8, BF16) | GLM-5.3 License |
| GLM-5.3-Flash | Open (FP8, BF16) | MIT |
| GLM-5.2, GLM-5.1, GLM-5 | Open (BF16, FP8) | MIT |
| GLM-4.7, GLM-4.7-Flash | Open | MIT |
| GLM-4.6, GLM-4.6V | Open | MIT |
| GLM-4.5, GLM-4.5-Air | Open | MIT |
| GLM-Image | Open | MIT |
| GLM-5-Turbo, FlashX, X, AirX | Not published | API only |
The one exception is GLM-5.3. Its GLM-5.3 License grants the same MIT-style permissions with one added condition: a licensee that runs a “Model as a Service” business and has aggregate revenue above $10 billion over any consecutive 12 months must pass Z.ai’s security review before commercial use. Building an end-user product with GLM-5.3 inside it, or relaying requests to a model hosted by someone else, does not count as Model as a Service. For almost every developer and company, GLM-5.3 behaves like an MIT model. Details and edge cases: is GLM open source.
Can you actually run them? GLM-4.7-Flash (31B total, 3B active) is the realistic home option: at BF16, the weights alone come to roughly 62 GB by simple arithmetic (31B parameters x 2 bytes), as an estimate. The 744B GLM-5 models are data-centre territory: the FP8 weights alone come to roughly 744 GB (1 byte per parameter), before any KV cache. Supported serving stacks include vLLM, SGLang, Transformers, KTransformers and Unsloth.
Open weights also mean you can adapt the model. Z.ai’s GLM-5 repository lists two fine-tuning routes for the GLM-5 series: slime (v0.3.0 or later), the reinforcement-learning framework the GLM team itself uses, and ms-swift (v4.4.0 or later), which supports SFT, PPO and GRPO. Under MIT you can keep, sell or redistribute the result.
Who makes GLM (Z.ai / Zhipu)
GLM is made by Z.ai, the company formerly known as Zhipu AI (often just “Zhipu”). It was founded in 2019 and grew out of research at Tsinghua University. On January 8, 2026 it listed on the Main Board of HKEX under stock code 2513 as Knowledge Atlas Technology, and was described at the time as the first publicly listed foundation-model company. In July 2026 the listed company changed its name to Z.AI Co., Ltd.
Besides the models, Z.ai runs the consumer chat app chat.z.ai, the developer platform and API at z.ai/model-api with docs at docs.z.ai, the GLM Coding Plan, an agentic desktop app called ZCode, and AutoClaw. Code and weights live on GitHub and Hugging Face. Z.ai’s earlier milestones include GLM-4-Voice and AutoGLM (October 2024), the GLM-Zero-Preview reasoning model (December 2024) and GLM-Realtime (January 2025).
Watch out for look-alike sites. Z.ai’s chat app, docs, API console and Coding Plan all live on z.ai and its subdomains, and there is no official status page at status.z.ai. The official GLM links page lists every genuine URL, and the Zhipu AI company profile covers the history, stock and products in depth.
GLM FAQ
What is the latest GLM model?
GLM-5.3 is the latest flagship, announced on August 14, 2026, with a 1M-token context and 744B total parameters. GLM-5.3-Flash, released on August 26, 2026, is the newest model overall: a cheaper 320B multimodal model that reads images and video. Z.ai has not announced a date or specs for GLM-5.5 or GLM-6.
Is GLM free to use?
Yes, in several ways. GLM Chat gives you nine GLM models with no account, chat.z.ai is Z.ai’s free web chat, and GLM-4.7-Flash, GLM-4.5-Flash and GLM-4.6V-Flash cost $0 on the Z.ai API. The larger models, including GLM-5.3 and GLM-5.3-Flash, are paid on the API.
Is GLM AI good for coding?
Coding is GLM’s strongest area. Z.ai reports GLM-5.3 at 88.2 on Terminal Bench 2.1 and 66.9 on DeepSWE v1.1, close to the top closed models, and the GLM Coding Plan connects it to Claude Code, Cline, Cursor, OpenCode and other agents. For a free option, GLM-4.7-Flash scores 59.2 on SWE-bench Verified according to its model card.
How big is GLM’s context window?
GLM-5.3, GLM-5.3-Flash and GLM-5.2 read up to 1M tokens and write up to 128K. GLM-5.1, GLM-5, GLM-4.7, GLM-4.7-Flash and GLM-4.6 have a 200K context. GLM-4.5 and GLM-4.5-Air have 128K with up to 96K output.
How much does the GLM API cost?
Per million tokens: GLM-5.3, GLM-5.2 and GLM-5.1 cost $1.40 in and $4.40 out, GLM-5 costs $1.00 and $3.20, GLM-5.3-Flash $0.15 and $0.50, GLM-4.7 $0.60 and $2.20, and GLM-4.7-Flash is free. Cached input is much cheaper, for example $0.26 on GLM-5.3. GLM-Image costs $0.015 per picture.
Can GLM read images?
Yes. GLM-5.3-Flash accepts images, video and files natively, and you can upload a JPEG, PNG or WebP (up to 4 MB) to it in GLM Chat. On the API, the dedicated vision models GLM-4.6V, GLM-4.6V-FlashX, GLM-4.5V and the free GLM-4.6V-Flash also read images. GLM-5.3 and GLM-5.2 are text-only.
Can I run GLM on my own computer?
The smaller open models, yes. GLM-4.7-Flash (31B total, 3B active) runs with vLLM or SGLang, and GLM-4.5-Air (106B total, 12B active) is a step up. The 744B GLM-5 line needs multi-GPU server hardware. All of these weights are on Hugging Face under zai-org.
What is the difference between GLM and ChatGLM?
ChatGLM was the name of Z.ai’s chat-tuned models from 2023, including the open-source ChatGLM-6B that passed 20 million downloads. Today the models are simply called GLM (GLM-4.5 through GLM-5.3), and the consumer chat app lives at chat.z.ai.