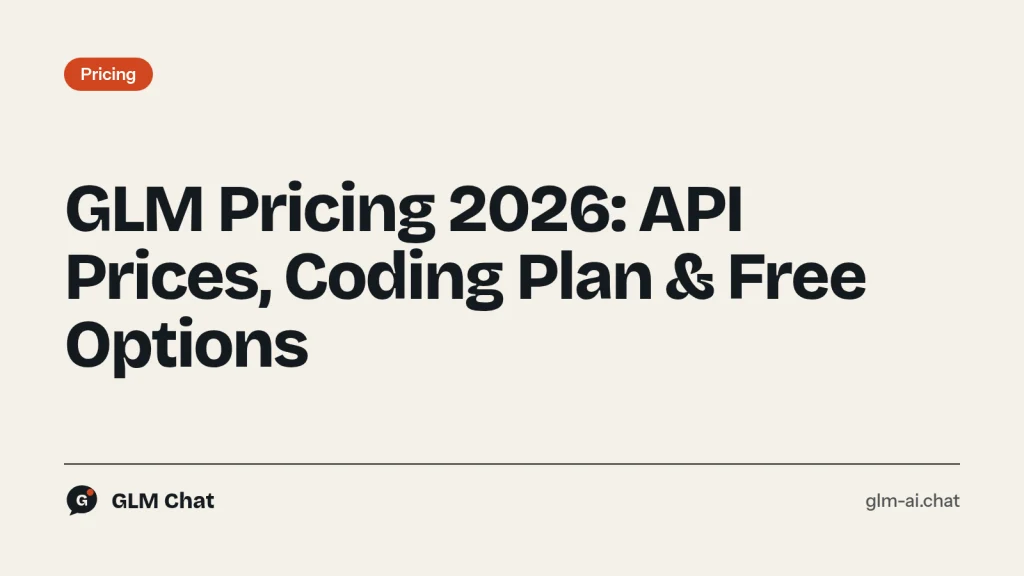
GLM pricing on the Z.ai API runs from free (GLM-4.7-Flash, GLM-4.5-Flash and GLM-4.6V-Flash cost nothing per token) up to $1.40 per 1M input tokens and $4.40 per 1M output tokens for the flagship GLM-5.3, GLM-5.2 and GLM-5.1. The cheapest current-generation model, GLM-5.3-Flash, costs $0.15 in and $0.50 out. Cached input is billed at roughly one fifth of the normal input price, and cache storage is free for a limited time.
If you code with agents all day, the flat-rate GLM Coding Plan costs $18, $80 or $168 per month (less with quarterly or yearly billing) and usually beats pay-as-you-go. If you only want to talk to the models, you do not need to pay anything: the free GLM chat on this site runs every current model without sign-up. This page lists every price Z.ai (formerly Zhipu AI) publishes, then shows the arithmetic so you can estimate your own bill.
GLM pricing at a glance
Z.ai sells GLM access in three ways. Pick the one that matches how you work, because the same workload can cost ten times more on the wrong route.
- Pay-as-you-go API. You top up a balance and pay per token (or per image, video or tool call). Best for apps, scripts, batch jobs and anything that runs outside a coding tool. Prices are per 1M tokens and split into input, cached input and output.
- GLM Coding Plan. A monthly subscription (Lite, Pro, Max, plus Team seats) that gives you a credit allowance every 5 hours and every week. It works only inside supported coding tools such as Claude Code, Cline, OpenCode, Cursor, ZCode and AutoClaw. Plan quota never draws from your API balance, and it cannot be used for general API calls.
- Free routes. Three API models are free per token, the chat.z.ai web app is free, OpenRouter lists a free rate-limited GLM-5.2 variant, and this site’s chat gives you daily messages on the paid models plus unlimited GLM-4.7-Flash.
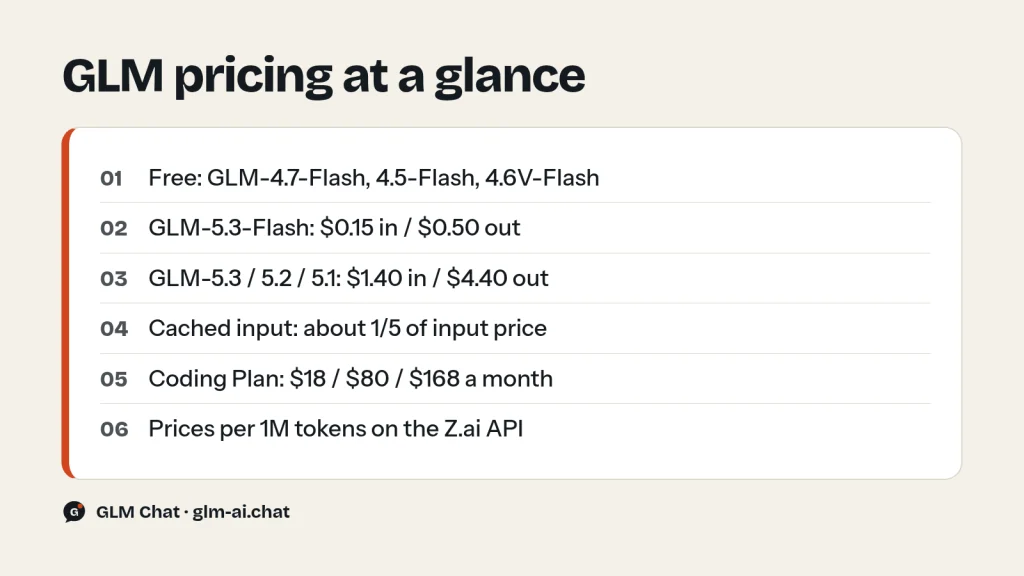
Z.ai API pricing for GLM text models
These are the pay-as-you-go prices from Z.ai’s official pricing page (docs.z.ai/guides/overview/pricing). All prices are in dollars per 1M tokens. “Cached input” is what you pay for input tokens that hit the context cache; the storage of cached input is listed as limited-time free for every paid model below except GLM-4-32B-0414-128K, which has no cached price.
| Model | Input | Cached input | Output | Model ID |
|---|---|---|---|---|
| GLM-5.3 | $1.40 | $0.26 | $4.40 | glm-5.3 |
| GLM-5.2 | $1.40 | $0.26 | $4.40 | glm-5.2 |
| GLM-5.1 | $1.40 | $0.26 | $4.40 | glm-5.1 |
| GLM-5 | $1.00 | $0.20 | $3.20 | glm-5 |
| GLM-5.3-FlashX | $0.37 | $0.075 | $1.25 | glm-5.3-flashx |
| GLM-5.3-Flash | $0.15 | $0.03 | $0.50 | glm-5.3-flash |
| GLM-4.7 | $0.60 | $0.11 | $2.20 | glm-4.7 |
| GLM-4.7-FlashX | $0.07 | $0.01 | $0.40 | glm-4.7-flashx |
| GLM-4.7-Flash | Free | Free | Free | glm-4.7-flash |
| GLM-4.6 | $0.60 | $0.11 | $2.20 | glm-4.6 |
| GLM-4.5 | $0.60 | $0.11 | $2.20 | glm-4.5 |
| GLM-4.5-X | $2.20 | $0.45 | $8.90 | glm-4.5-x |
| GLM-4.5-Air | $0.20 | $0.03 | $1.10 | glm-4.5-air |
| GLM-4.5-AirX | $1.10 | $0.22 | $4.50 | glm-4.5-airx |
| GLM-4.5-Flash | Free | Free | Free | glm-4.5-flash |
| GLM-4-32B-0414-128K | $0.10 | – | $0.10 | glm-4-32b-0414-128k |
Three things stand out. First, the whole flagship line (GLM-5.3, GLM-5.2 and GLM-5.1) shares one price, so there is no cost reason to stay on an older flagship. Second, the “X” variants (GLM-5.3-FlashX, GLM-4.7-FlashX, GLM-4.5-X, GLM-4.5-AirX) are faster, pricier versions of their base models; GLM-5.3-FlashX, for example, runs at around 200 tokens per second according to Z.ai. Third, output tokens cost roughly three to six times more than input on nearly every paid model, so long answers and heavy reasoning drive most bills.
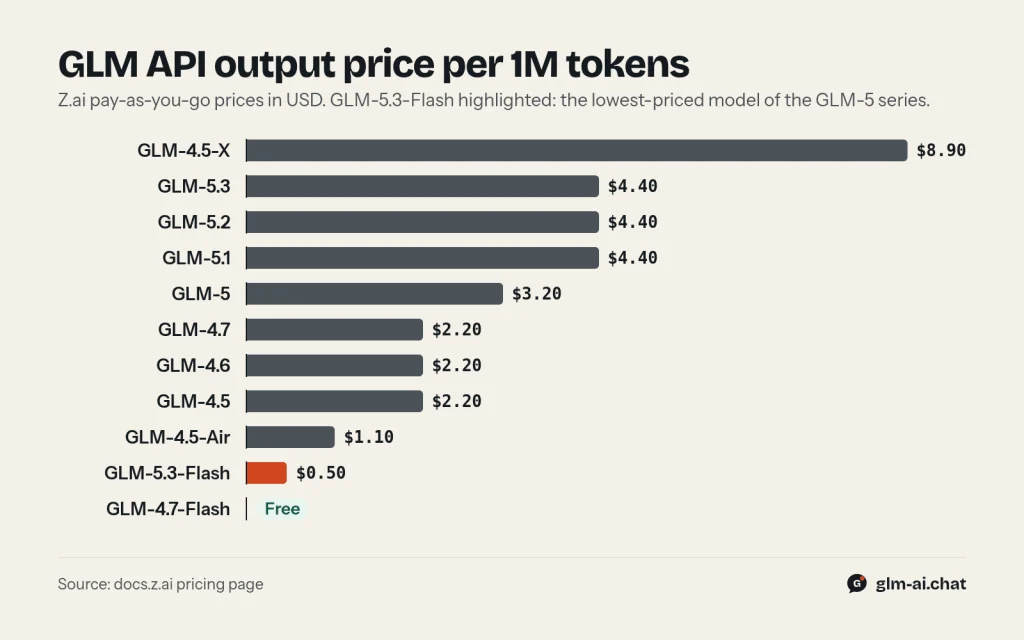
GLM-5-Turbo pricing
GLM-5-Turbo, the GLM-5 variant tuned for OpenClaw agent workflows, does not appear on Z.ai’s public pricing page. OpenRouter lists it as z-ai/glm-5-turbo at $1.20 input and $4.00 output per 1M tokens. On Z.ai itself, the Coding Plan subscription page names GLM-5-Turbo for agents, so the plan is the main way most people reach it. See GLM with OpenClaw for when Turbo is the right pick.
Vision, image, video, audio and tool pricing
Z.ai’s multimodal and utility models use the same per-token structure where they read text or images, and per-item prices where they generate media. GLM-5.3-Flash is itself natively multimodal (video, image, text and file input), so for most image-understanding tasks it is the model to price first.
| Vision model | Input | Cached input | Output |
|---|---|---|---|
| GLM-4.6V | $0.30 | $0.05 | $0.90 |
| GLM-4.6V-FlashX | $0.04 | $0.004 | $0.40 |
| GLM-4.6V-Flash | Free | Free | Free |
| GLM-4.5V | $0.60 | $0.11 | $1.80 |
| GLM-OCR | $0.03 | – | $0.03 |
| Product | Type | Price |
|---|---|---|
| GLM-Image | Image generation | $0.015 per image |
| CogView-4 | Image generation | $0.01 per image |
| CogVideoX-3 | Video generation | $0.20 per video |
| GLM-ASR-2512 | Speech recognition | $0.03 per 1M tokens (about $0.0024 per minute) |
| Web Search (built-in tool) | Tool call | $0.01 per use |
| GLM Slide/Poster Agent (beta) | Agent | $0.70 per 1M tokens |
| General-Purpose Translation | Agent | $3 per 1M tokens |
| Special Effects Video Templates | Agent | $0.20 per video |
Two details matter here. GLM-Image returns a URL to the generated picture, and that link expires after 30 days, so download anything you want to keep. And the built-in Web Search tool adds $0.01 per search on top of the tokens the model reads, which adds up fast in agent loops that search on every turn. The GLM web search API guide covers how to limit that.
GLM-5.2 pricing and cost
GLM-5.2 costs $1.40 per 1M input tokens, $0.26 per 1M cached input tokens and $4.40 per 1M output tokens on the Z.ai API, exactly the same as GLM-5.3 and GLM-5.1. Its 1M-token context window does not carry a long-context surcharge on the published price list: a request is billed by the tokens it uses.
What does that mean in practice? A single request that fills 800,000 tokens of context costs 0.8 × $1.40 = $1.12 in input alone if nothing is cached. The same request with 90% of those tokens served from cache costs (0.08 × $1.40) + (0.72 × $0.26) = $0.112 + $0.187 = about $0.30. That gap is why long-context agents only make economic sense with caching.
GLM-5.2 is also cheaper on some third-party routers. OpenRouter lists z-ai/glm-5.2 at roughly $0.65 input and $2.04 output per 1M tokens (it routes across several providers, so the figure moves), plus a free variant, z-ai/glm-5.2:free, limited to a 32,768-token context and rate-limited. On the GLM Coding Plan, GLM-5.2 requests are now routed automatically to GLM-5.3. Full specs are on the GLM-5.2 model page.
Cached input pricing explained
Context caching is automatic on the Z.ai API. When a request repeats content the platform has recently processed (a long system prompt, a document you keep asking about, or earlier turns of a conversation), the repeated tokens are served from cache and billed at the cached-input rate instead of the full input rate. You do not set a flag or create a cache object.
- How much you save: Z.ai’s FAQ says cache hits are charged at approximately one fifth of the original price. The table bears that out: GLM-5.3 input is $1.40 and cached input is $0.26 (about 19%).
- Storage: cached-input storage is listed as “Limited-time Free” on the pricing page.
- Where to see it: each response reports cached tokens in
usage.prompt_tokens_details.cached_tokens. Subtract that fromprompt_tokensto get the tokens billed at the full rate. - What breaks it: caching keys on identical or highly similar content. Z.ai notes that minor formatting differences can reduce cache hits, and that cached content expires after a time limit.
A response with cache usage looks like this:
{
  "usage": {
    "prompt_tokens": 1200,
    "completion_tokens": 300,
    "total_tokens": 1500,
    "prompt_tokens_details": {
      "cached_tokens": 800
    }
  }
}
On GLM-5.3 that request costs (400 × $1.40 + 800 × $0.26 + 300 × $4.40) / 1,000,000 = (560 + 208 + 1,320) / 1,000,000 ≈ $0.0021. Without the cache hit it would be (1,200 × $1.40 + 300 × $4.40) / 1,000,000 = $0.0030. The step-by-step guide to structuring prompts for cache hits is in GLM context caching.
Worked cost examples
The formula for any token-priced GLM model is simple:
cost = (uncached_input × input_price
      + cached_input × cached_price
      + output × output_price) / 1,000,000
Example 1: 1,000 requests of 2K in and 500 out
A typical chatbot or classification job: 1,000 requests, each with 2,000 input tokens and 500 output tokens, no caching. That is 2,000,000 input tokens (2M) and 500,000 output tokens (0.5M) in total.
| Model | Input cost | Output cost | Total | Per request |
|---|---|---|---|---|
| GLM-5.2 or GLM-5.3 | 2 × $1.40 = $2.80 | 0.5 × $4.40 = $2.20 | $5.00 | $0.005 |
| GLM-5 | 2 × $1.00 = $2.00 | 0.5 × $3.20 = $1.60 | $3.60 | $0.0036 |
| GLM-4.7 | 2 × $0.60 = $1.20 | 0.5 × $2.20 = $1.10 | $2.30 | $0.0023 |
| GLM-5.3-FlashX | 2 × $0.37 = $0.74 | 0.5 × $1.25 = $0.625 | $1.365 | $0.0014 |
| GLM-4.5-Air | 2 × $0.20 = $0.40 | 0.5 × $1.10 = $0.55 | $0.95 | $0.00095 |
| GLM-5.3-Flash | 2 × $0.15 = $0.30 | 0.5 × $0.50 = $0.25 | $0.55 | $0.00055 |
| GLM-4.7-Flash | $0 | $0 | $0 | $0 |
The spread is roughly 9x between the flagship and GLM-5.3-Flash, and infinite against GLM-4.7-Flash. Run your prompts through the cheaper model first; move up only for the requests where quality clearly improves. You can compare answers side by side for free in GLM-5.3-Flash in the chat and GLM-5.2 in the chat before you commit.
Example 2: a coding agent with a large, repeated context
An agent makes 200 calls to GLM-5.3. Each call sends 100,000 input tokens (repo files, tool results, history), of which 90,000 repeat from the previous call and hit the cache, and returns 2,000 output tokens.
- Without caching: input 200 × 100,000 = 20M tokens × $1.40 = $28.00. Output 200 × 2,000 = 0.4M × $4.40 = $1.76. Total $29.76.
- With 90% cache hits: cached 18M × $0.26 = $4.68. Uncached 2M × $1.40 = $2.80. Output $1.76. Total $9.24, a 69% saving.
- Same run on GLM-5.3-Flash with caching: 18M × $0.03 = $0.54, plus 2M × $0.15 = $0.30, plus 0.4M × $0.50 = $0.20. Total $1.04.
Example 3: reasoning tokens on a hard question
GLM-5.3 and GLM-5.3-Flash always think before they answer, and GLM-5.2, GLM-5.1, GLM-5 and GLM-4.7 think by default. The reasoning text is generated output, so it is counted in completion_tokens and billed at the output price. If GLM-5.3 writes 6,000 reasoning tokens and a 1,000-token answer, you pay for 7,000 output tokens: 7,000 × $4.40 / 1,000,000 = $0.031. Setting reasoning_effort to "low" on GLM-5.3 (the default is "max") is the single biggest lever on that number. The GLM thinking mode guide lists the settings per model.
Example 4: images and search
A marketing workflow generates 500 GLM-Image posters: 500 × $0.015 = $7.50. A research agent that runs 3 web searches per question over 1,000 questions pays 3,000 × $0.01 = $30 for search alone, before any tokens. Tool calls are often the hidden cost in agent budgets.
GLM Coding Plan pricing
The GLM Coding Plan is Z.ai’s subscription for AI coding tools. Since July 30, 2026, individual plans are credits-based: every plan has a 5-hour credit limit and a weekly credit limit, and each request burns credits according to the tokens it uses. All plans include GLM-5.3 and GLM-5.3-Flash; requests for GLM-5.2 or GLM-5.1 are routed to GLM-5.3, and requests for GLM-4.7 are routed to GLM-5.3-Flash.
| Plan | Monthly billing | Quarterly (20% off) | Yearly (30% off) | 5-hour credits | Weekly credits |
|---|---|---|---|---|---|
| Lite | $18/month | $14.40/month | $12.60/month | 2,000 | 10,000 |
| Pro | $80/month | $64/month | $56/month | 12,000 | 60,000 |
| Max | $168/month | $134.40/month | $117.60/month | 28,000 | 140,000 |
Pro gives 6x the Lite usage and Max gives 14x. Beyond credits, the subscribe page lists these tier benefits: Lite is “built for lightweight iteration on small repo” with 20+ agent tools and default data privacy; Pro adds a curated selection of MCP tools, faster generation and priority access to the latest flagship models; Max adds first access to new models and dedicated resources during peak times. Every plan includes the Vision Understanding, Web Search, Web Reader and Zread MCP servers.
Team plan prices
| Seat | Monthly | Annual (10% off) | 5-hour credits | Weekly credits |
|---|---|---|---|---|
| Standard Seat | $88/seat | from $79.20/seat | 15,000 | 66,000 |
| Premium Seat | $188/seat | from $169.20/seat | 35,000 | 155,000 |
Team seats add centralized seat and permission management, usage dashboards, centralized billing and invoicing, and optional on-demand overage (billed, as a limited-time offer, at 10% off the API list price). Premium seats also get early access to new models and priority during peak hours.
How Coding Plan credits are calculated
credits = (input × input_multiplier
         + cached_input × cached_multiplier
         + output × output_multiplier) / 10,000

MCP tool call credits = number of calls × 1.2| Product | Input multiplier | Cached input multiplier | Output multiplier |
|---|---|---|---|
| GLM-5.3 | 6.9 | 1.7 | 24 |
| GLM-5.3-Flash (incl. vision MCP) | 2.3 | 0.56 | 8 |
| Web Search, Web Reader, Zread MCP | – | – | 1.2 per call |
Peak and off-peak. Peak hours are Monday to Friday, 14:00–18:00 UTC+8. Outside those hours, and all day on weekends, model usage is charged at 50% of the standard credit rate.
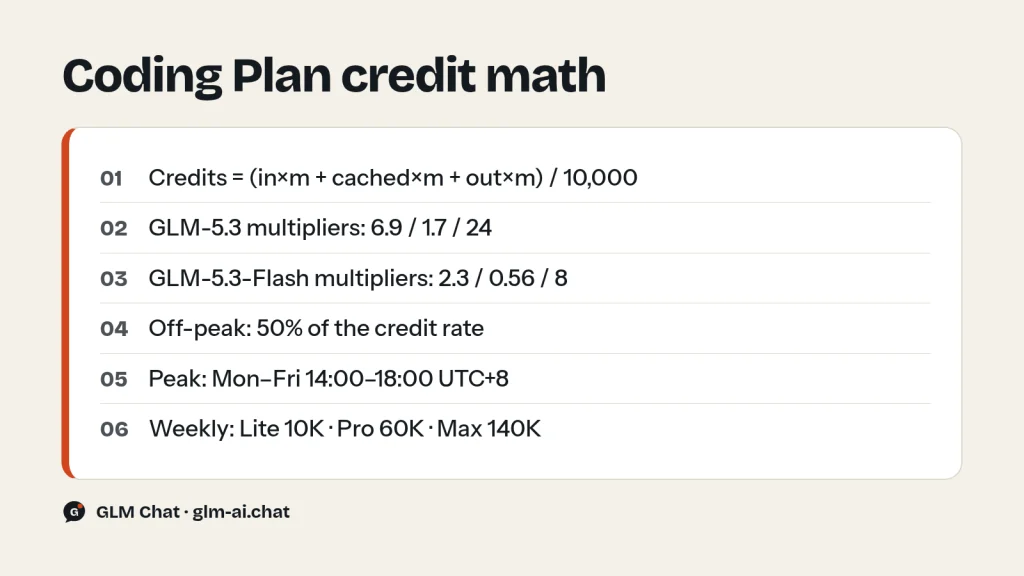
Credits math: what a Lite plan buys
Take one agent call on GLM-5.3 with 100,000 input tokens, 95,000 of them cached (so 5,000 uncached), and 2,000 output tokens:
- Uncached input: 5,000 × 6.9 = 34,500
- Cached input: 95,000 × 1.7 = 161,500
- Output: 2,000 × 24 = 48,000
- Sum 244,000 / 10,000 = 24.4 credits at peak, or 12.2 credits off-peak.
Lite’s 10,000 weekly credits cover about 409 of those calls if they all land in peak hours (10,000 / 24.4), or about 819 off-peak. The 5-hour cap of 2,000 credits allows about 81 peak calls per window. The same call on GLM-5.3-Flash costs (5,000 × 2.3 + 95,000 × 0.56 + 2,000 × 8) / 10,000 = (11,500 + 53,200 + 16,000) / 10,000 = 8.07 credits, so Lite covers roughly 1,239 of them per week at peak.
Compare the API. That GLM-5.3 call costs (5,000 × $1.40 + 95,000 × $0.26 + 2,000 × $4.40) / 1,000,000 = $0.007 + $0.0247 + $0.0088 = $0.0405 pay-as-you-go. 409 calls would be about $16.56 on the API, in a single week, while Lite costs $18 for the whole month. If you actually use the quota, the plan wins by a wide margin; if you code a few hours a month, the API can be cheaper. Z.ai claims plan users can save up to 92% against pay-as-you-go GLM-5.3 by making full use of off-peak discounts.
Z.ai’s estimated weekly token allowance
| Cache hit rate | Model | Lite (M tokens/week) | Pro (M tokens/week) | Max (M tokens/week) |
|---|---|---|---|---|
| 95% | GLM-5.3 | 48–97 | 290–580 | 676–1,352 |
| 95% | GLM-5.3-Flash | 146–292 | 877–1,755 | 2,047–4,095 |
| 98% | GLM-5.3 | 52–104 | 313–627 | 731–1,463 |
| 98% | GLM-5.3-Flash | 158–317 | 950–1,900 | 2,217–4,433 |
Other plan rules worth knowing before you pay: subscriptions are non-refundable, so cancel auto-renewal at least 24 hours before the renewal date; upgrading to a higher tier applies immediately with prorated credit; the plan only works in supported tools; and an “1113 Insufficient Balance” error while subscribed usually means the tool is pointed at the wrong base URL (the plan uses https://api.z.ai/api/coding/paas/v4 for OpenAI-compatible tools and https://api.z.ai/api/anthropic for Claude Code). Legacy prompt-based plans sold before July 30, 2026 keep their terms until the current billing cycle ends. Setup steps are in GLM in Claude Code.
Free ways to use GLM
You can get a lot done with GLM without spending anything. Here are the real free routes and their limits.
| Route | Models | Limits |
|---|---|---|
| GLM Chat (this site) | GLM-5.3-Flash, GLM-5.3, GLM-5.2, GLM-5.1, GLM-4.7, GLM-4.6, GLM-4.5, GLM-4.7-Flash, GLM-Image | 40 messages/day on paid models; GLM-4.7-Flash unlimited (one request every 3 s); 3 images/day; no sign-up |
| chat.z.ai | Z.ai’s current GLM models | Free web chat app from Z.ai |
| Z.ai API, free models | GLM-4.7-Flash, GLM-4.5-Flash, GLM-4.6V-Flash | Free input, cached input and output; your account’s rate limits apply |
| OpenRouter free variant | z-ai/glm-5.2:free | $0, 32,768-token context, rate-limited |
Be precise about “free” when you read other sites. GLM-5.3-Flash is free to use in this site’s chat, where it is the default model, but on the Z.ai API it costs $0.15 in and $0.50 out. GLM-4.7-Flash is the one current model that is genuinely free per token on the API, and it is a capable 30B-A3B model with a 200K context. The GLM-4.7-Flash page shows how to call it at zero cost.
To call the free model, use the standard endpoint with its model ID:
curl https://api.z.ai/api/paas/v4/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $ZAI_API_KEY" \
  -d '{
    "model": "glm-4.7-flash",
    "messages": [{"role": "user", "content": "Summarize the GLM pricing tiers in 3 bullets."}]
  }'
OpenRouter prices for GLM models
OpenRouter is a third-party router that resells GLM access alongside other providers. Its listed prices differ from Z.ai’s, sometimes lower, because several hosts serve the open weights. Prices change often: treat the table as OpenRouter’s listed price and confirm on the model’s OpenRouter page before you budget.
| OpenRouter slug | Input / 1M | Output / 1M | Context |
|---|---|---|---|
z-ai/glm-5.3 | $1.40 | $4.40 | 1,310,720 |
z-ai/glm-5.3:batch | $0.45 | $2.00 | – |
z-ai/glm-5.3-flash | $0.15 | $0.50 | – |
z-ai/glm-5.3-flashx | $0.37 | $1.25 | – |
z-ai/glm-5.2 | about $0.65 | about $2.04 | 1,048,576 |
z-ai/glm-5.2:free | $0 | $0 | 32,768 |
z-ai/glm-5.1 | $0.97 | $3.04 | 204,800 |
z-ai/glm-5-turbo | $1.20 | $4.00 | – |
z-ai/glm-5 | $0.60 | $1.92 | – |
z-ai/glm-4.7 | $0.40 | $1.75 | – |
z-ai/glm-4.7-flash | $0.06 | $0.40 | – |
z-ai/glm-4.6 | $0.43 | $1.75 | – |
z-ai/glm-4.5 | $0.60 | $2.20 | – |
z-ai/glm-4.5-air | $0.13 | $0.85 | – |
Note one reversal: GLM-4.7-Flash is free on Z.ai’s own API but costs money on OpenRouter. For older open models such as GLM-5.1, GLM-5 and GLM-4.7, OpenRouter’s listed rates run below Z.ai’s; for GLM-5.3 and GLM-5.3-Flash they match. OpenRouter also sells a batch variant of GLM-5.3 at $0.45 in and $2.00 out, which suits offline jobs that can wait.
How to cut your GLM API bill
- Start on the cheapest model that passes. Test GLM-4.7-Flash (free) and GLM-5.3-Flash ($0.15/$0.50) before reaching for the $1.40/$4.40 flagship. The GLM models comparison shows what each tier is good at.
- Turn reasoning down. Reasoning tokens are output tokens. On GLM-5.3 and GLM-5.3-Flash pass
"reasoning_effort": "low"(thinking cannot be disabled there). On GLM-5.2,"none"skips thinking. On GLM-5.1, GLM-5 and GLM-4.7 send"thinking": {"type": "disabled"}for simple tasks. - Cap output. Set
max_tokensto what you really need. Output costs several times more than input on almost every paid model. - Design for cache hits. Keep system prompts and long documents byte-identical and at the start of the message list; append new turns at the end. Cached input costs about a fifth of fresh input.
- Trim conversation history. Every past turn you resend is billed again as input (cached or not). Summarize old turns in long sessions.
- Control tool calls. Each built-in web search costs $0.01. Let the model search only when the question needs fresh facts.
- Move heavy coding to the Coding Plan, and schedule long agent runs off-peak (outside Monday to Friday, 14:00–18:00 UTC+8) to halve credit use.
- Watch the bill with a delay in mind. Z.ai’s billing history shows the previous day’s consumption, so today’s usage is not visible immediately. Check the billing page at z.ai/manage-apikey/billing daily during a new rollout.
If requests start failing rather than costing more, see GLM API rate limits and error codes: a 429 with code 1113 means your balance is empty (or, on the plan, a wrong base URL), while 1302 and 1305 are rate and capacity limits. New to the API? The GLM API quickstart gets you from key to first request in minutes.
GLM pricing FAQ
How much does the GLM API cost?
For text models, between $0 and $2.20 per 1M input tokens and between $0 and $8.90 per 1M output tokens, depending on the model. The current flagships (GLM-5.3, GLM-5.2, GLM-5.1) cost $1.40 in and $4.40 out; GLM-5.3-Flash costs $0.15 in and $0.50 out; GLM-4.7-Flash, GLM-4.5-Flash and GLM-4.6V-Flash are free.
How much does GLM-5.2 cost per request?
It depends on tokens. A request with 2,000 input and 500 output tokens costs (2,000 × $1.40 + 500 × $4.40) / 1,000,000 = $0.005 on the Z.ai API. Reasoning tokens count as output, so thinking-heavy requests cost more.
Is there a free GLM API?
Yes. GLM-4.7-Flash, GLM-4.5-Flash and GLM-4.6V-Flash are free on the Z.ai API for input, cached input and output. You still need an API key, and your account’s rate limits apply.
Is GLM-5.3-Flash free?
It is free to chat with on this site (it is the default model), but not on the Z.ai API, where it costs $0.15 per 1M input tokens and $0.50 per 1M output tokens. That is still about one ninth of the flagship price.
How much is the GLM Coding Plan?
Lite is $18 per month, Pro $80 and Max $168 on monthly billing. Quarterly billing takes 20% off and yearly billing 30% off, which brings Lite to $12.60, Pro to $56 and Max to $117.60 per month. Team seats cost $88 (Standard) or $188 (Premium) per seat per month.
Can I use Coding Plan credits for normal API calls?
No. The plan works only inside supported coding tools through the Coding Plan base URLs, and its quota never draws from or adds to your API balance. For apps and scripts, pay per token.
What is cached input on Z.ai?
Input tokens that repeat content the platform has recently processed, such as a fixed system prompt or earlier conversation turns. They are billed at the cached rate (for GLM-5.3, $0.26 instead of $1.40 per 1M), and caching happens automatically.
Is GLM cheaper on OpenRouter?
For some models, yes. OpenRouter’s listed prices for GLM-5.2, GLM-5.1, GLM-5 and GLM-4.7 are below Z.ai’s, and it offers a free, rate-limited z-ai/glm-5.2:free. For GLM-5.3 and GLM-5.3-Flash the listed prices match Z.ai’s, and GLM-4.7-Flash is cheaper on Z.ai (free). Always confirm on OpenRouter before budgeting.
Want to see which model is worth paying for? Try the same prompt on a few of them in the free GLM chat, then check the GLM release timeline to make sure you are pricing the latest version.